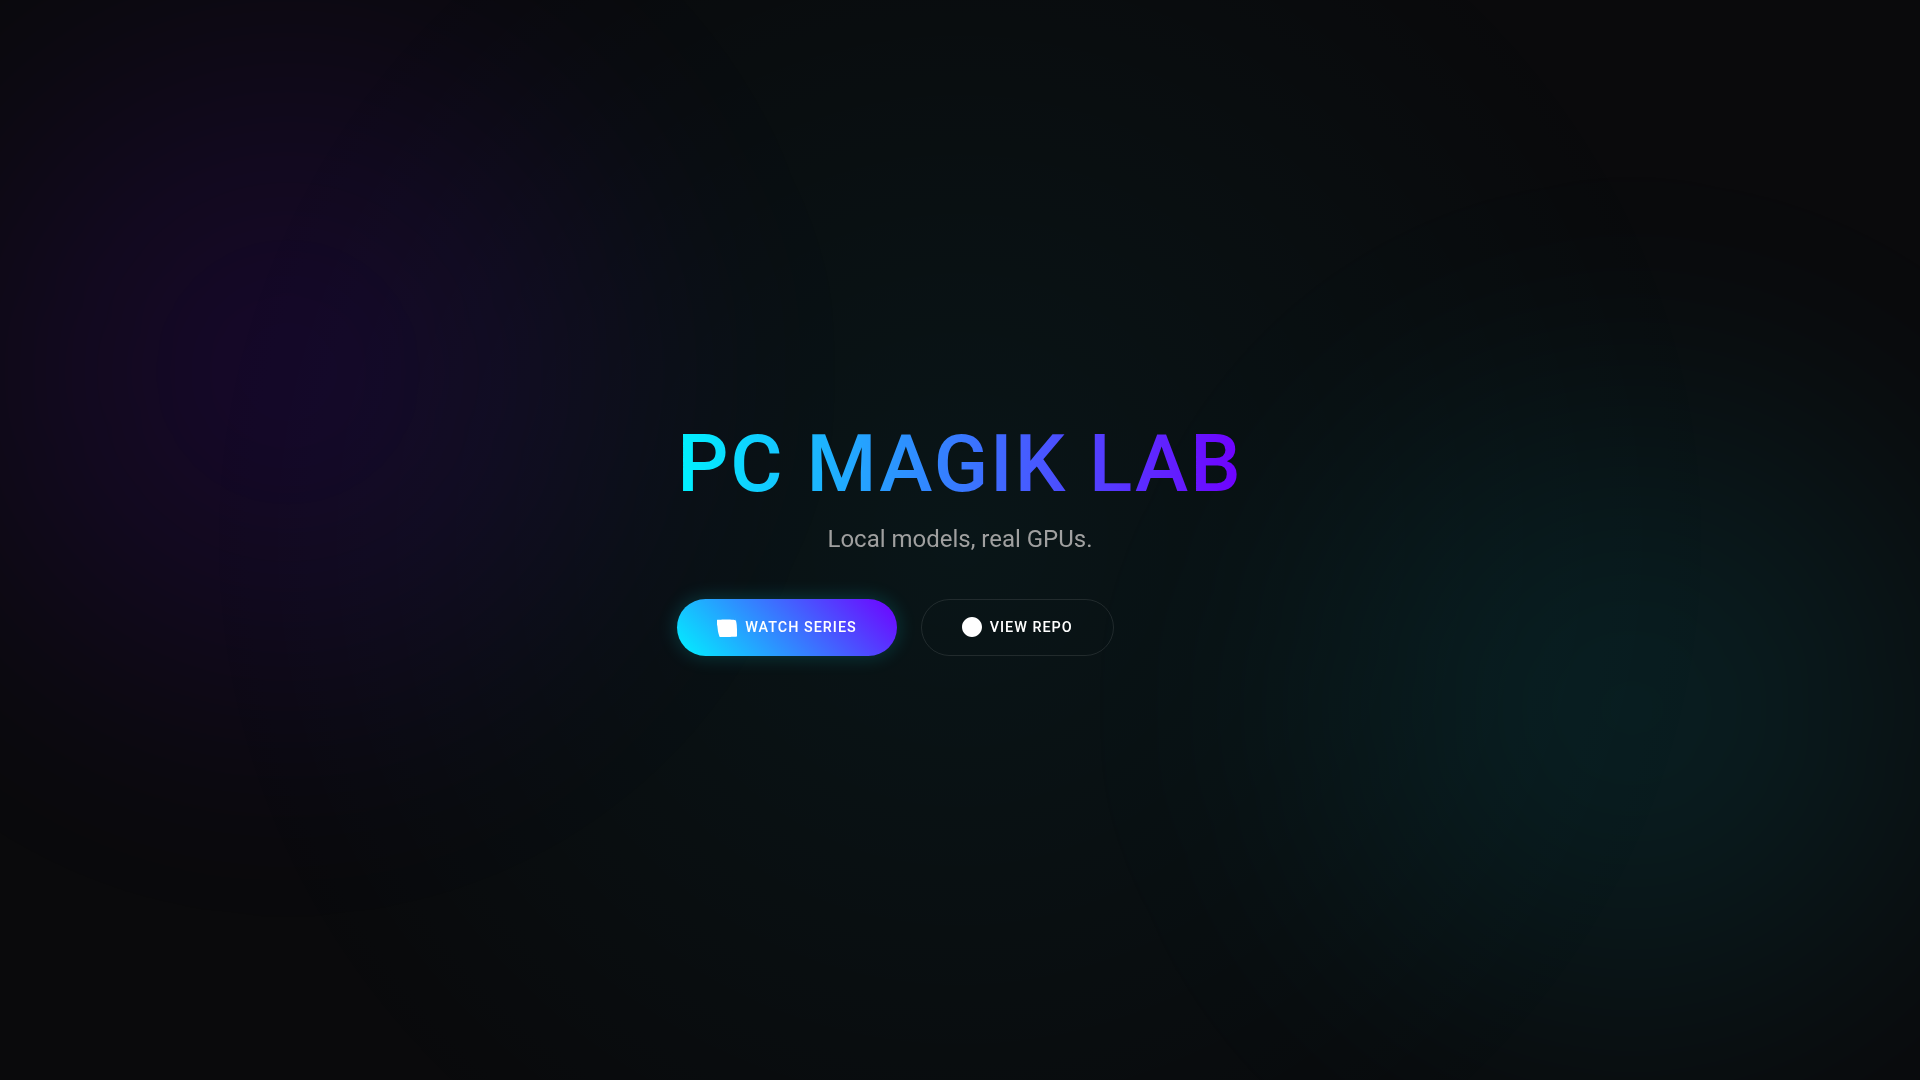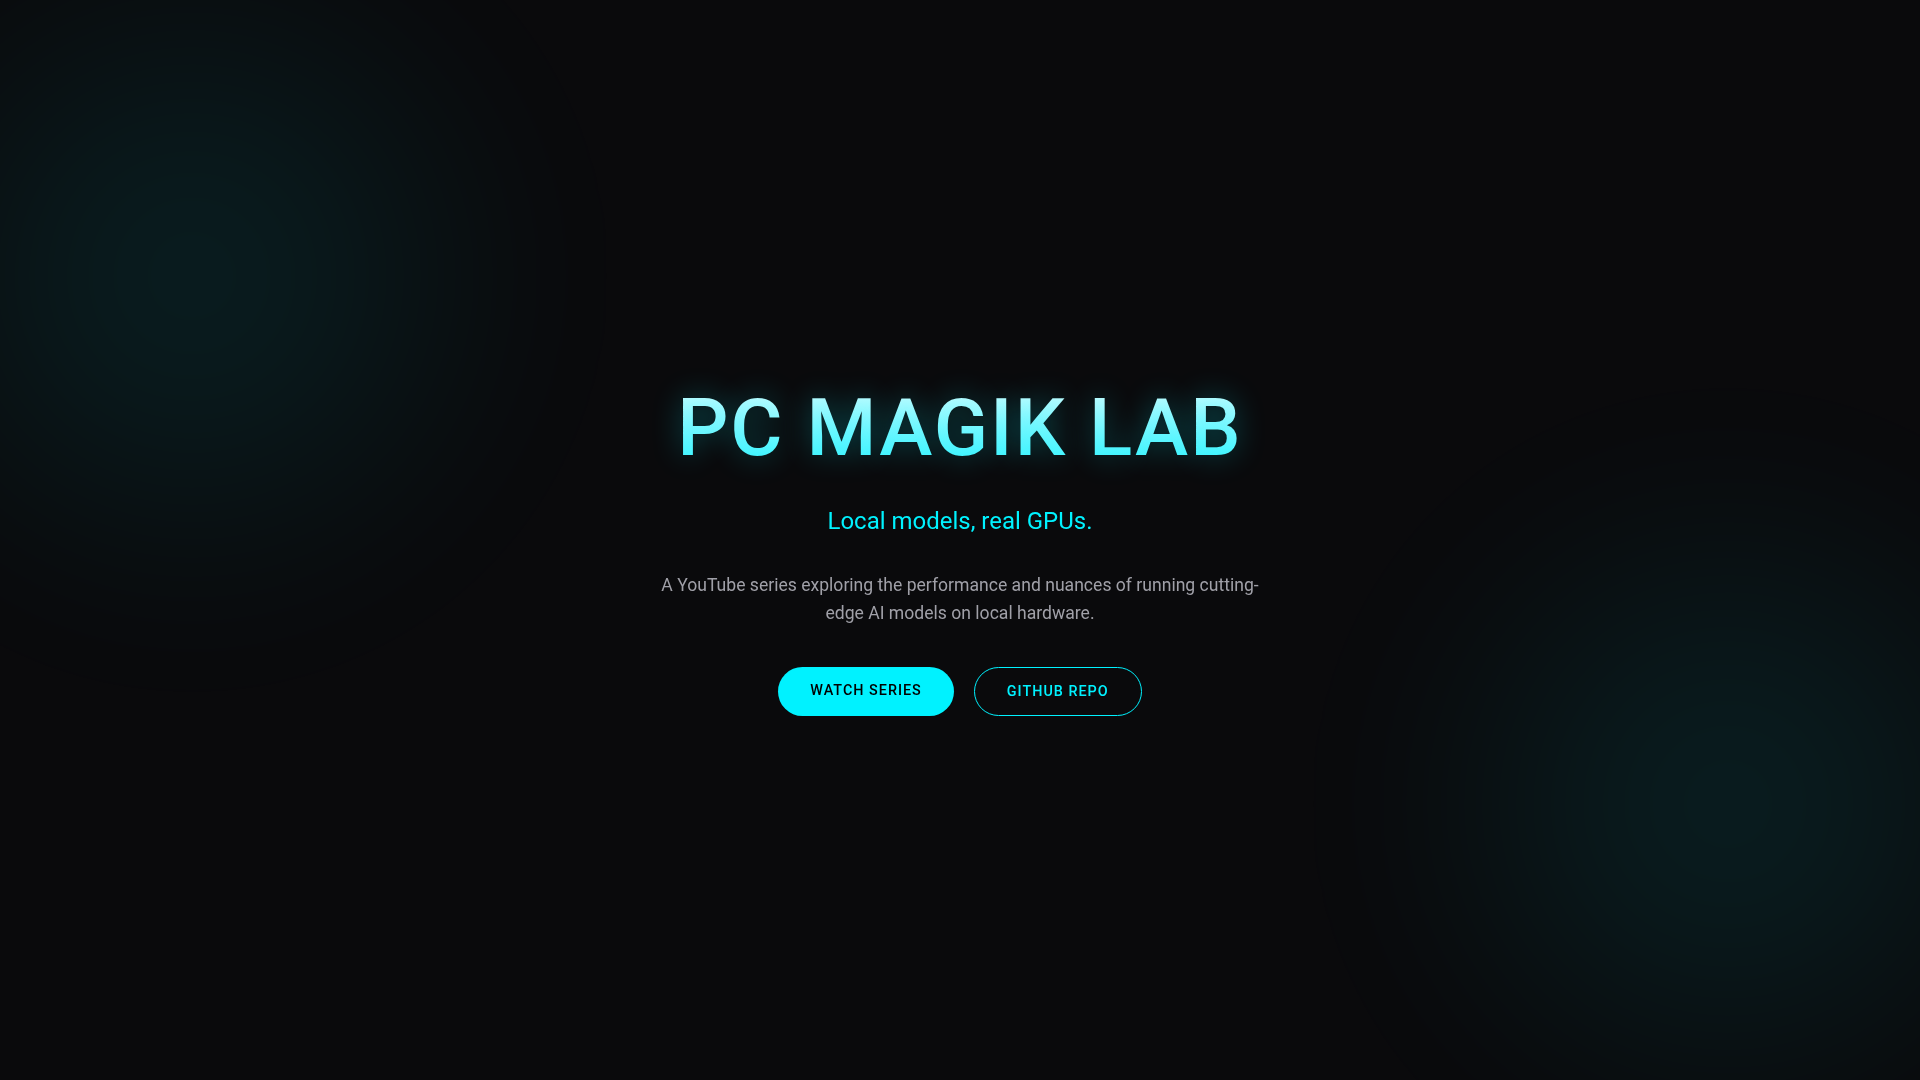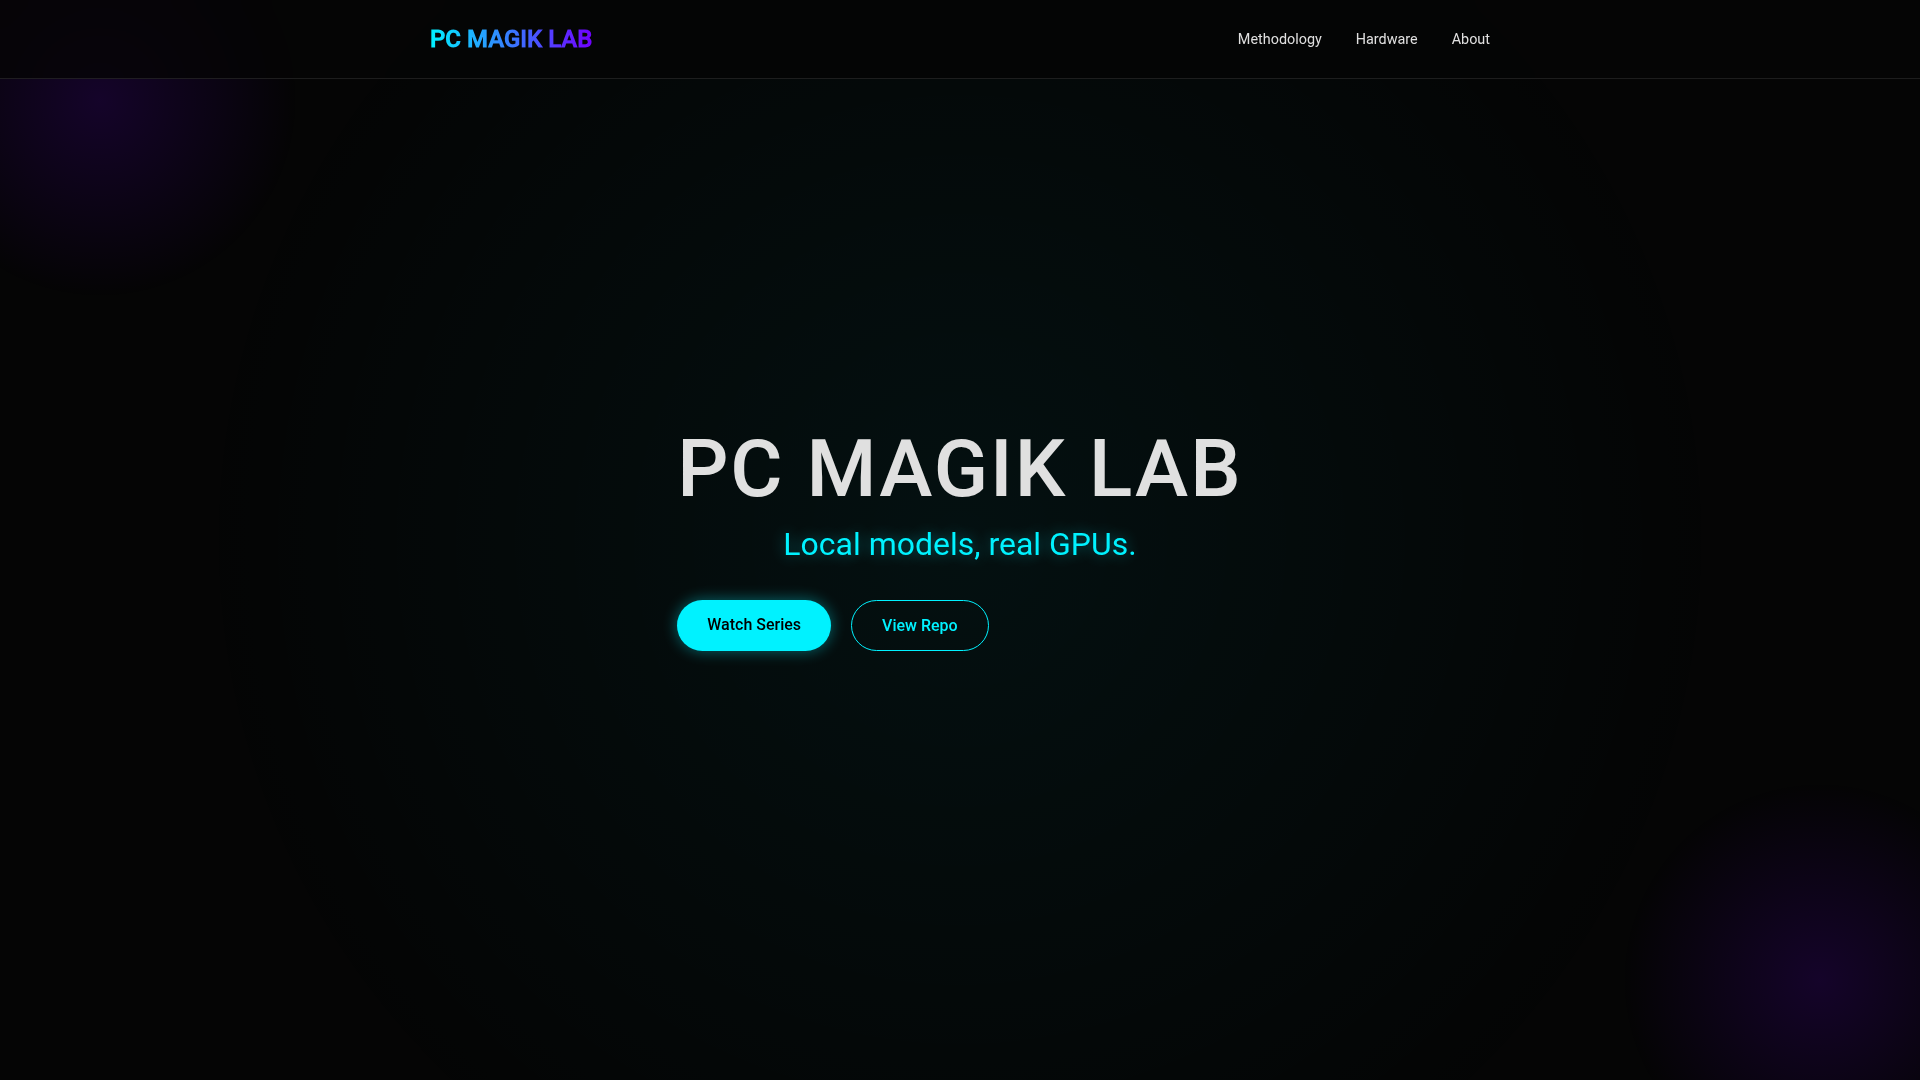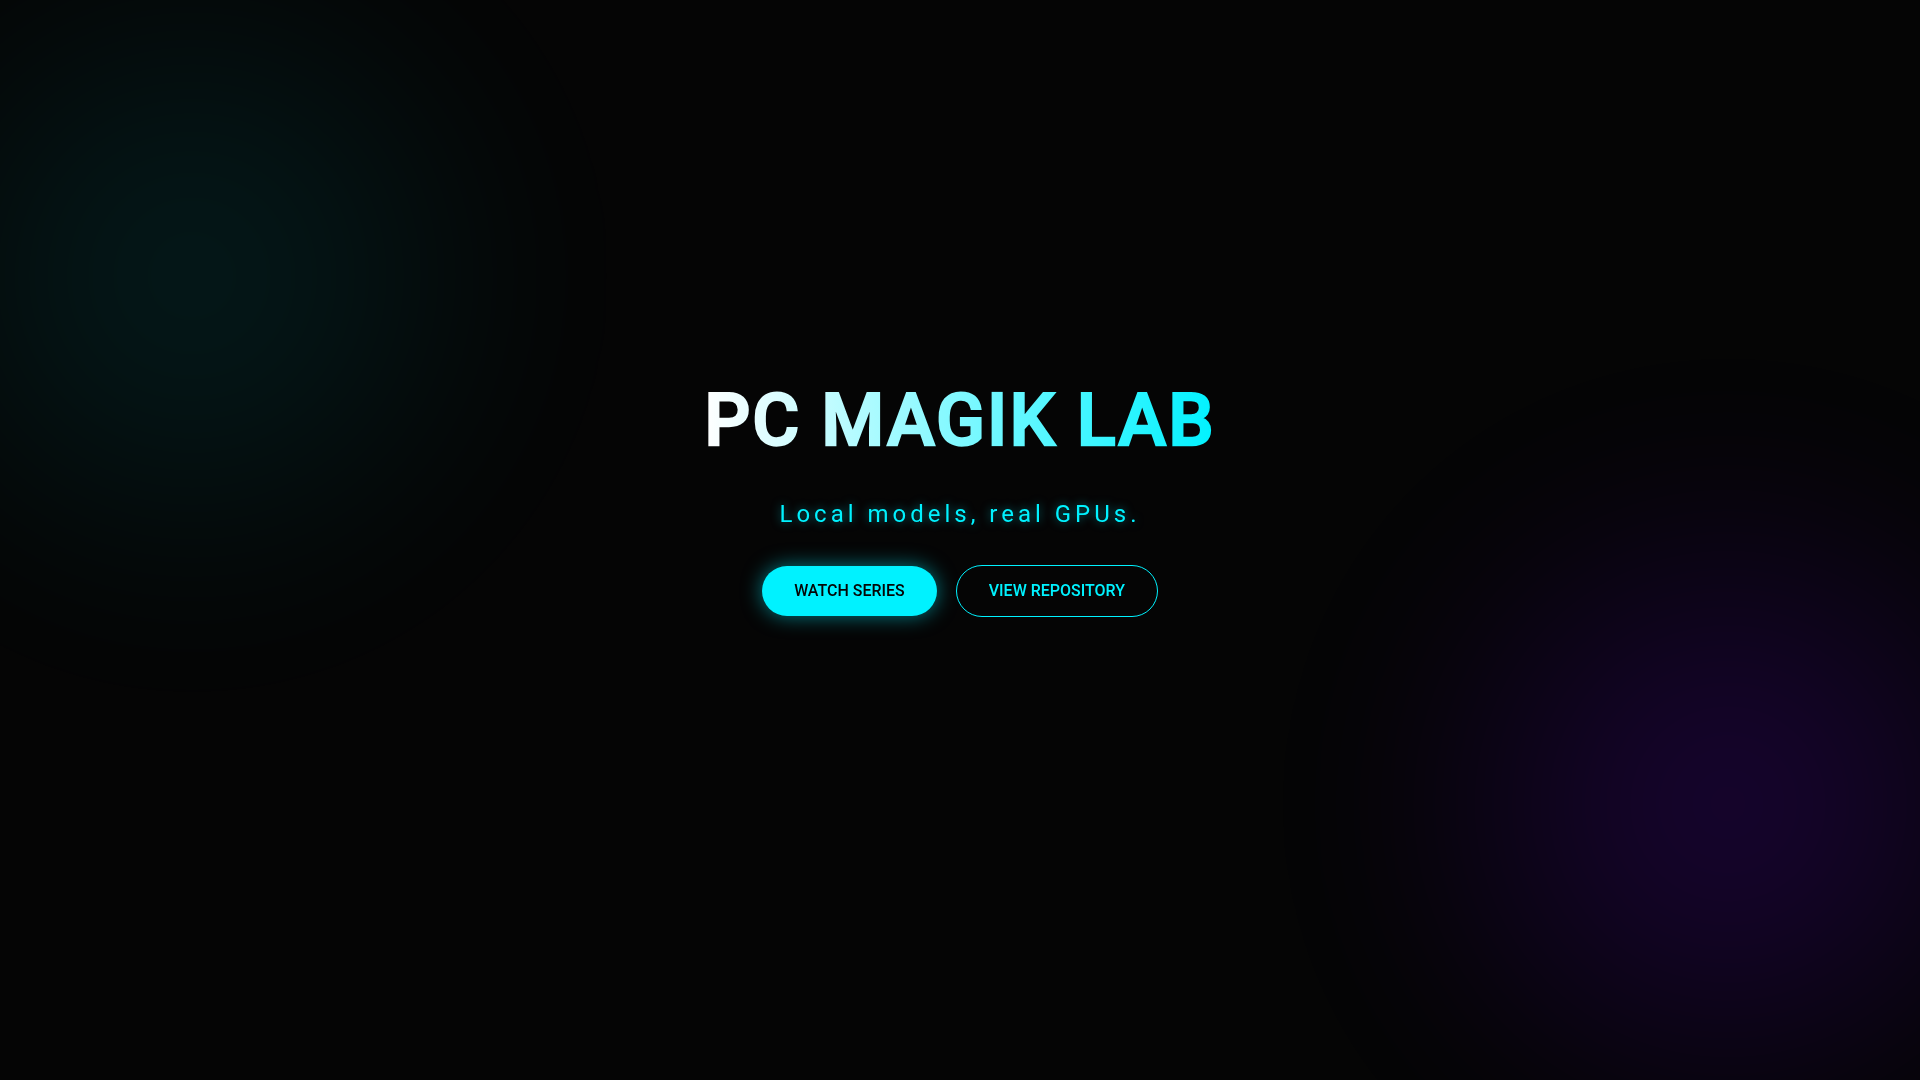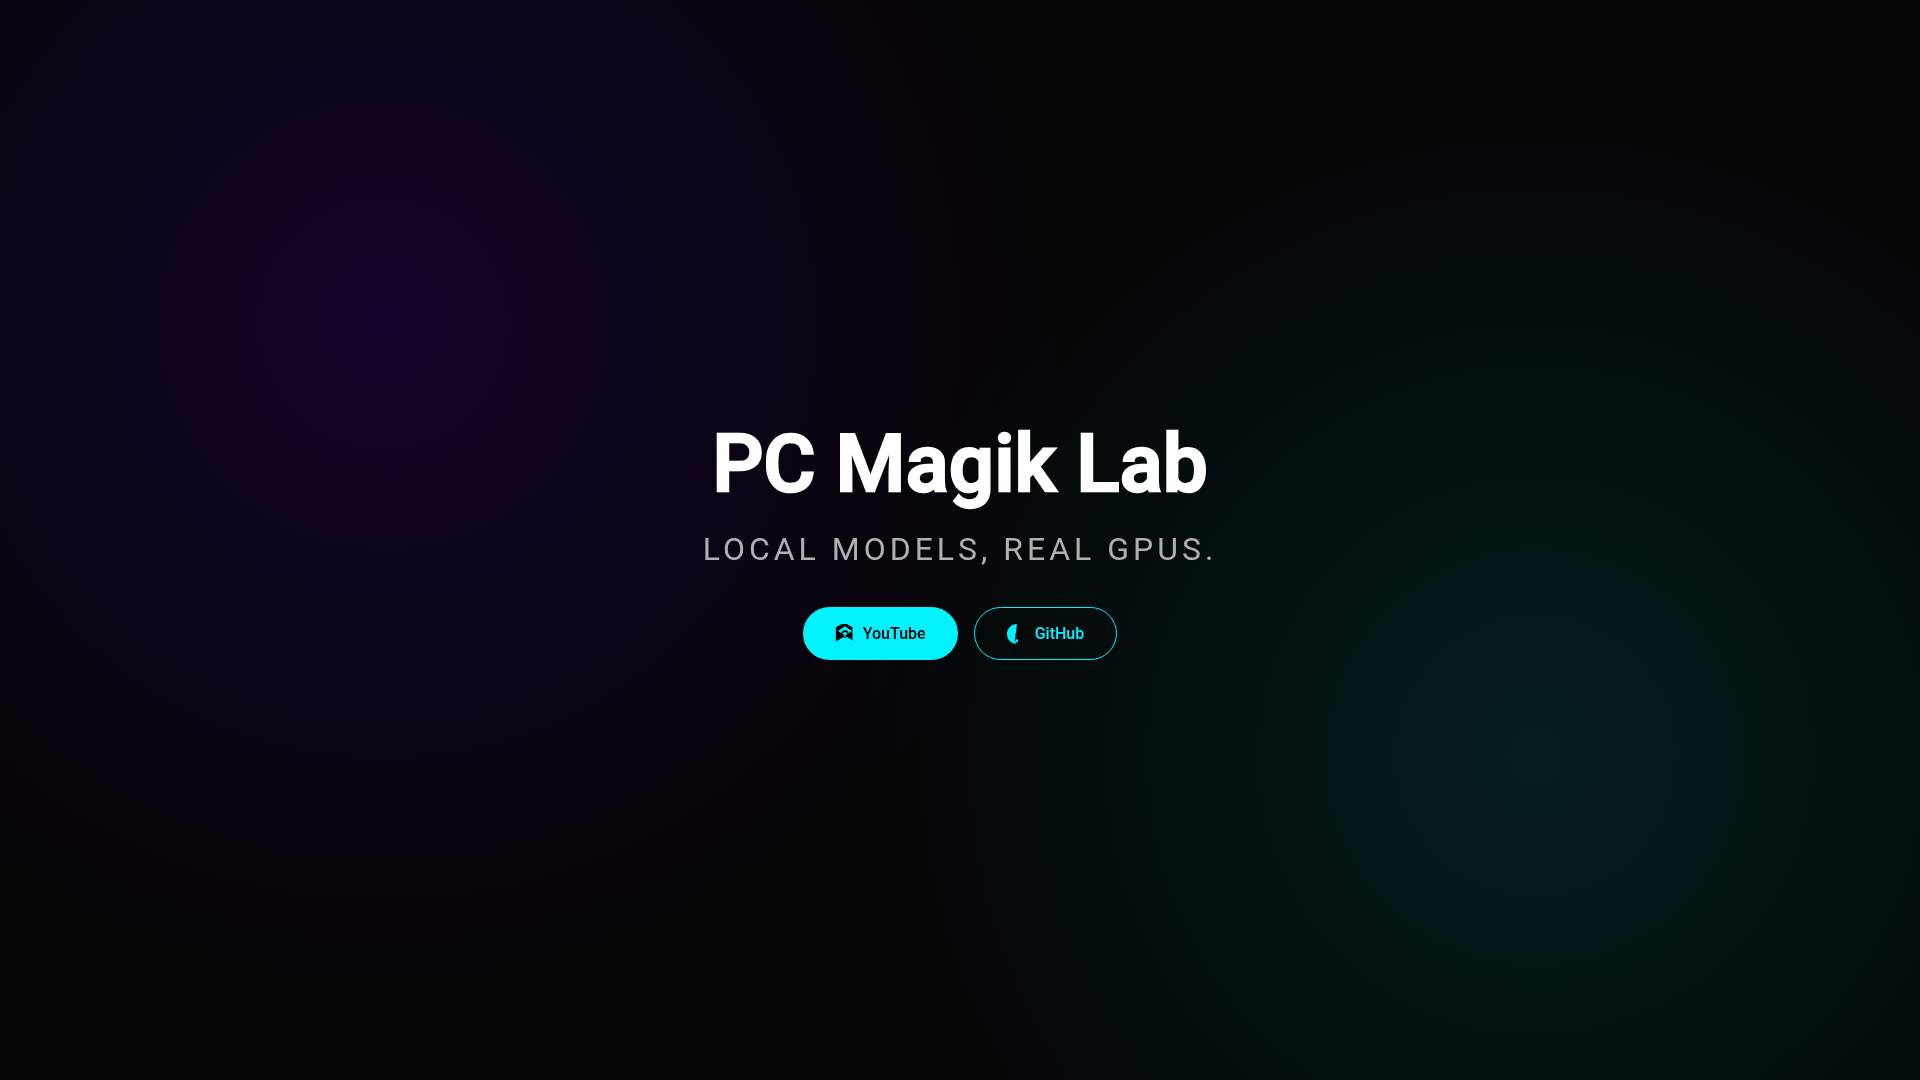
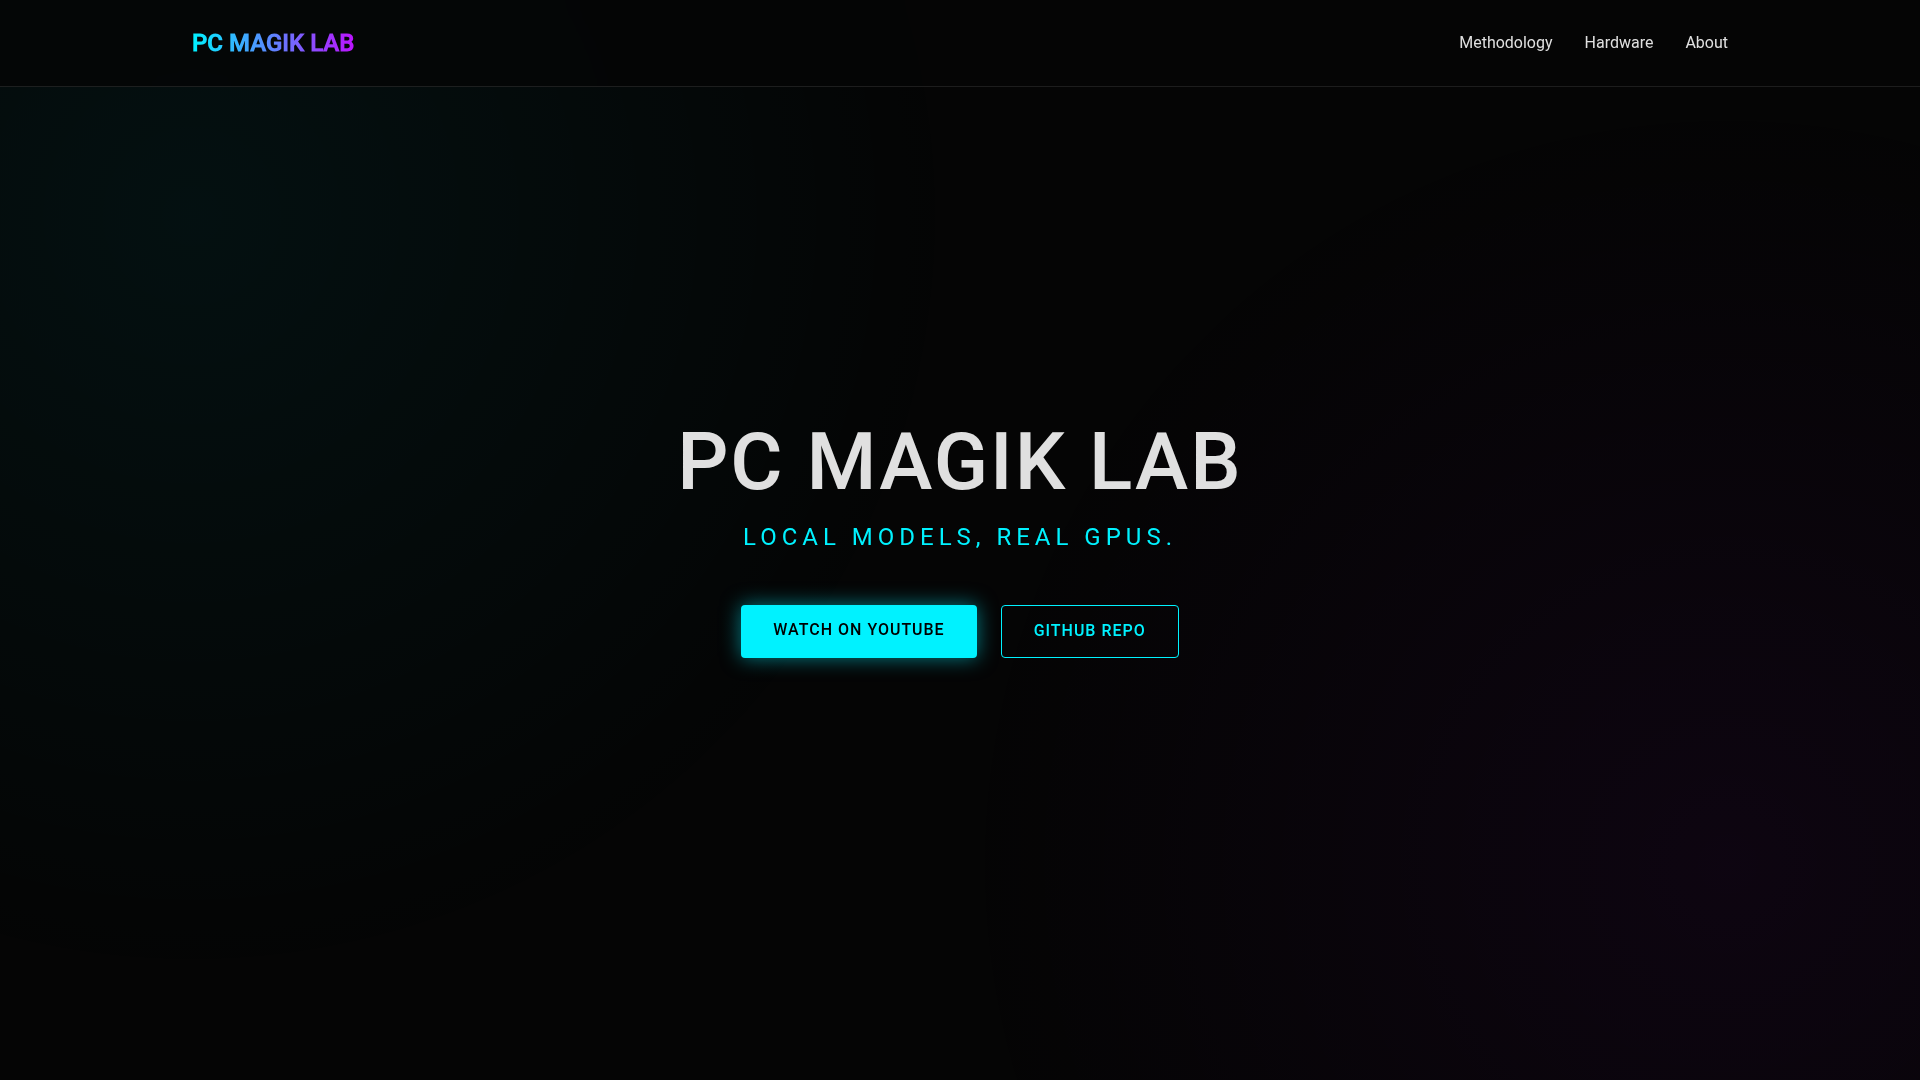
Run 1
2:35 min:stime
17,251output tokens
10.0%thinking
111.41tok/s
479lines of code
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_bare_r1
google/gemma-4-26b-a4b-qat
Same model, same prompt, same rig. 3 runs with nothing added, 3 with one Karpathy rules file.
google/gemma-4-26b-a4b-qat
Ranges overlap (counted effects)Effects count CSS/JS constructs, not visual quality.

Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.

Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_bare_r1
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_bare_r2
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_bare_r3
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_karpathy_r1
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_karpathy_r2
Effort requested: medium; received: on · differs from requested effort · source: metrics.json. Effort is not comparable across models.
gemma-4-26b-a4b-qat_karpathy_r3
output = thinking + final code. Lines of code show the page size the model chose, not the cost of equivalent work.
Settings recorded for these runs. Multiple values show differences between runs. Effort is requested, not necessarily received; it is not comparable across models. Hover over quantization, K/V cache or engine values for their sources.
| Model | Quantization | Context window | K/V cache | max_tokens | Engine | Harness | Effort requested |
|---|---|---|---|---|---|---|---|
| google/gemma-4-26b-a4b-qat | Q4_0 | 262,144 | K f16 / V f16 (LM Studio default) | 131,072 | [email protected] | pi 0.85.1 | medium |
REPRODUCE THE EXPERIMENT
Compare runs within the same model. Inspect the shared prompt, settings and raw measurements in the repository.